
Your team's AI disagrees. Find out what changed.
Contents
When AI answers disagree
Compare the evidence first.
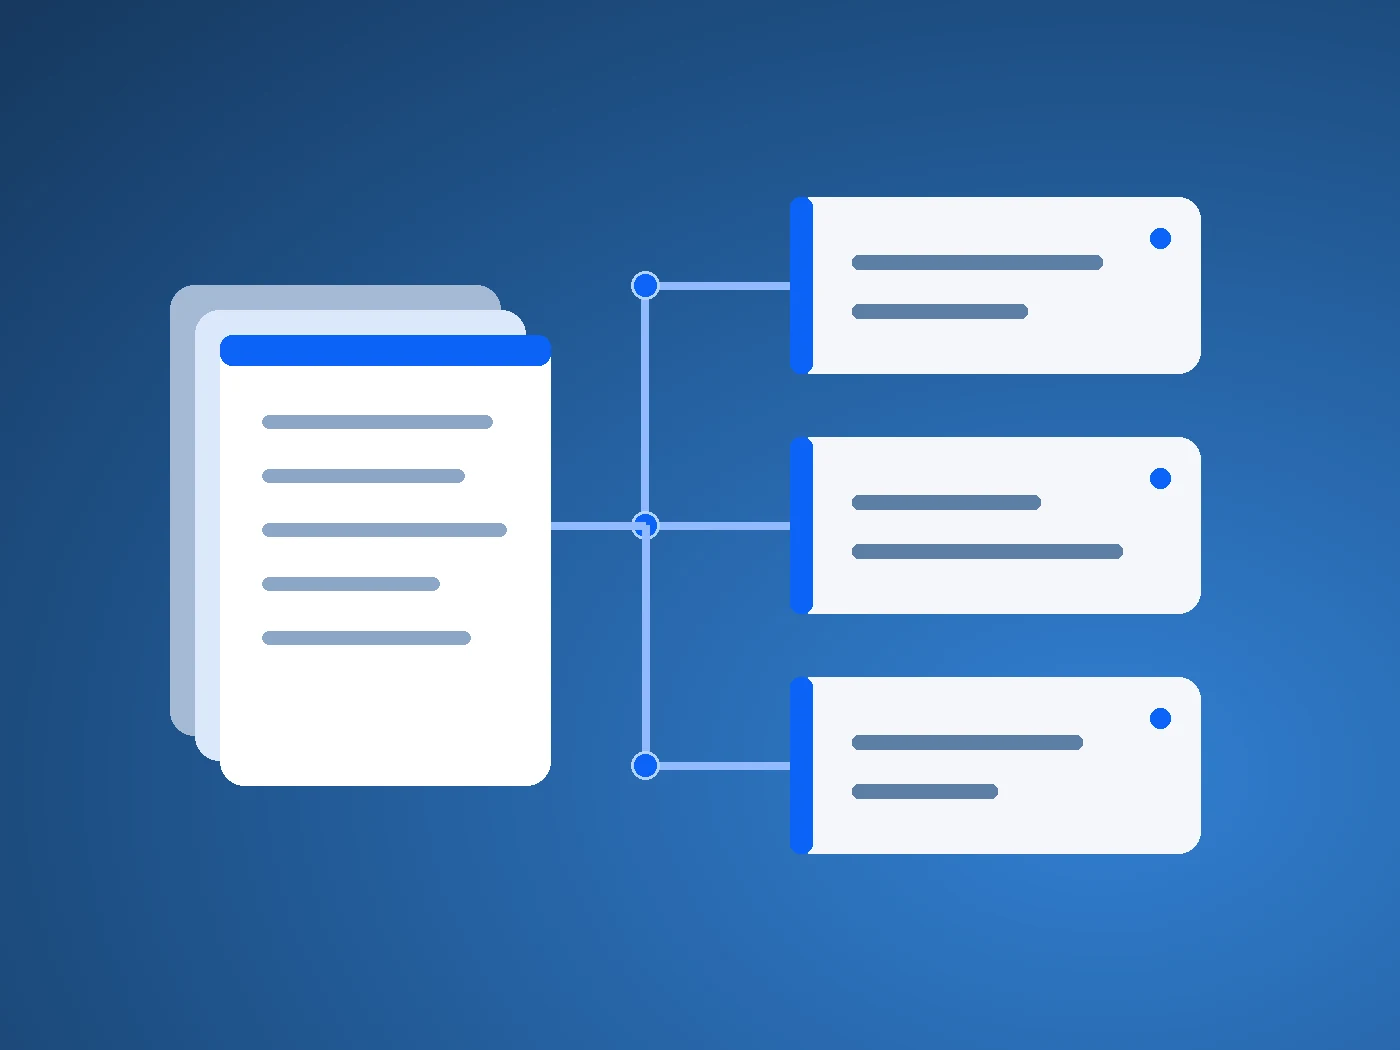
Three teammates ask whether a customer can renew under an old contract. One assistant says yes, another says no, and a third recommends asking Legal. Before you decide which AI is better, check whether they answered the same question with the same evidence. Different wording can be harmless. Different commitments need an explanation. Here is a way to locate that difference without uploading everyone's chat history into one place.
- Compare the decision-relevant claims, not whether the sentences match.
- Record the question, authorised evidence, instructions and model conditions for each answer.
- Change one condition at a time when a controlled comparison is feasible.
- Do not resolve legitimate access differences by giving everyone more permissions.
- Agree on supported facts and acceptable uncertainty before judging the next run.
First decide whether the answers actually conflict
Imagine this fictional renewal question: ‘Can this customer keep the old terms next month?’ One answer quotes the general policy. Another relies on a signed amendment. A third has neither and declines to decide. The differences may come from their evidence, the account in question, or their permission to read the amendment. They are not proof that one model is unreliable.
Rewrite each answer as a short claim with conditions: ‘Old terms apply to account A until date B, according to source C.’ If the date and scope agree, a warmer tone or shorter explanation is not the problem. If one answer invents an exception, that is a substantive failure even if every teammate receives the same confident sentence.
Choose what you need to make consistent. A brainstorm can benefit from varied ideas. An internal policy answer needs supported conditions, dates and limitations. Agreement alone cannot establish correctness: several assistants can repeat the same obsolete document.
Capture a comparison card before editing anything
Use the card below for two answers about one bounded question. It is an original editorial worksheet, not a software feature or a validated benchmark. Record the important differences while the question and evidence are still available. If your client does not expose a condition, mark it unknown; do not guess its hidden prompt or model settings.
Keep access checks local to the authorised owner. A source identifier, version and permission status can help diagnose a mismatch without copying restricted passages to colleagues. Even identifiers may be sensitive. Share only what your organisation permits, and have an authorised reviewer inspect the restricted material when necessary.
| Condition | What to compare |
|---|---|
| Question and scope | Exact question; account, period, audience and decision requested. |
| Evidence | Authorised source references, versions or checked dates; what was actually supplied or retrieved. |
| Identity and access | Which test identity was used; whether it could read the relevant source. Do not copy credentials. |
| Instructions and history | Relevant visible instructions and prior conversation; unknown hidden instructions stay unknown. |
| Model and settings | Exposed model/version and settings, if available; distinguish an app label from a verified version. |
| Answer and support | Decision-relevant claim, cited passage or source gap, and acceptable uncertainty. |
Separate changed inputs from generation variability
OpenAI’s evaluation guidance explains that generative systems can produce different outputs from the same input. It recommends task-specific evaluations rather than relying on a general impression that an answer looks good. That means a comparison must allow for variation in expression while checking the facts that matter.
For a controlled exercise, use a fresh test conversation, the same bounded question and the same permitted source packet. Hold the exposed model and settings constant where possible. Record what you could not control. Repeat the request a few times to see whether the substantive conclusion changes. This is a diagnostic suggestion; a handful of answers does not estimate a reliable failure rate or prove production consistency.
Next change one condition deliberately. Supply the clearly marked current document instead of the archived version, or make the question’s account scope explicit. If the result changes, you have a useful lead. You have not proved that this was the only cause: retrieval, hidden app instructions and other unobserved conditions may also differ. Changing the model, sources and prompt together makes that lead harder to interpret.
Work through the renewal example
In this hypothetical company, the general policy says renewals use current terms. A signed amendment says account A may keep its old terms until 31 December. A planning note proposes ending that exception earlier but records no approval. These documents and dates are invented to illustrate the exercise; they are not a Brain customer story or a reported product test.
Before running an assistant, the authorised policy owner writes the expected answer: for account A, the signed amendment establishes the exception until its stated end date; the proposal is not a replacement decision. For another account, the example provides no such exception. If the amendment is unavailable to the test identity, the assistant should report that the general policy alone cannot establish this account’s exception.
Compare the claim and the supporting source. An answer based only on the policy suggests a missing or unused amendment. An answer that treats the proposal as approved suggests an authority error. An answer that quotes a restricted amendment to an unauthorised user raises a different issue: stop that exposure and follow the organisation’s incident process. More consistent wording would not solve it.
Do not ask a model to arbitrate a genuine policy dispute by sounding certain. If the documents do not establish which rule applies, name the conflict and ask the accountable owner to resolve it. A maintained source of truth is a human and operational responsibility; adding a larger context window does not supply missing approval.
Judge support and uncertainty separately
Anthropic’s evaluation documentation recommends specific, measurable success criteria and separates task fidelity, consistency and other dimensions. Apply that distinction to your own task: decide which facts must be present, which assertions must not be made, and when a limited answer is acceptable.
For the fictional renewal case, a simple review records three things: did the answer use the applicable source, did it keep the account and date conditions intact, and did it avoid claiming an approval that the packet does not contain? Record each finding separately. A fluent paragraph can still fail the approval check; an honest limitation can be the correct result.
Keep examples with known expectations for future changes. Include an ordinary question, an outdated source, a missing account-specific document and a genuinely unresolved conflict. Use appropriate authorised test identities for access cases. These are starting cases for your team’s review, not a complete security test or a certification of any assistant.
Fix the layer that produced the disagreement
If the right document never reached the assistant, investigate source availability and retrieval. If it arrived but was treated as a suggestion, make its status and scope understandable. If the documents themselves disagree, resolve ownership and approval. If the inputs were comparable and important claims still varied, evaluate the model and the surrounding application against your task criteria.
Each fix has a cost. Manual source packets are inspectable but take effort to prepare. Automatic retrieval can reduce that effort but adds coverage and freshness questions. Reusing conversation history can preserve context while also carrying an earlier assumption forward. Broader access may hide a test failure by exposing information that should remain restricted. Keep the permission boundary while you improve the answer.
Choose one recurring question this week. Capture two comparison cards, write the supported facts and acceptable limitations, and change one condition in a permitted test. Keep the before-and-after evidence and the unresolved unknowns. That gives the next person something more useful than ‘the AI was inconsistent.’ For help selecting the packet, use our context engineering worksheet; for personal records, see the AI second brain guide.
Editorial method: HeyBrain Editorial Team drafted this article with AI assistance and checked the linked primary documentation. The comparison card and diagnostic sequence are editorial recommendations. The renewal scenario is fictional; no model experiment, integration, customer result or HeyBrain capability was tested for this article.